ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
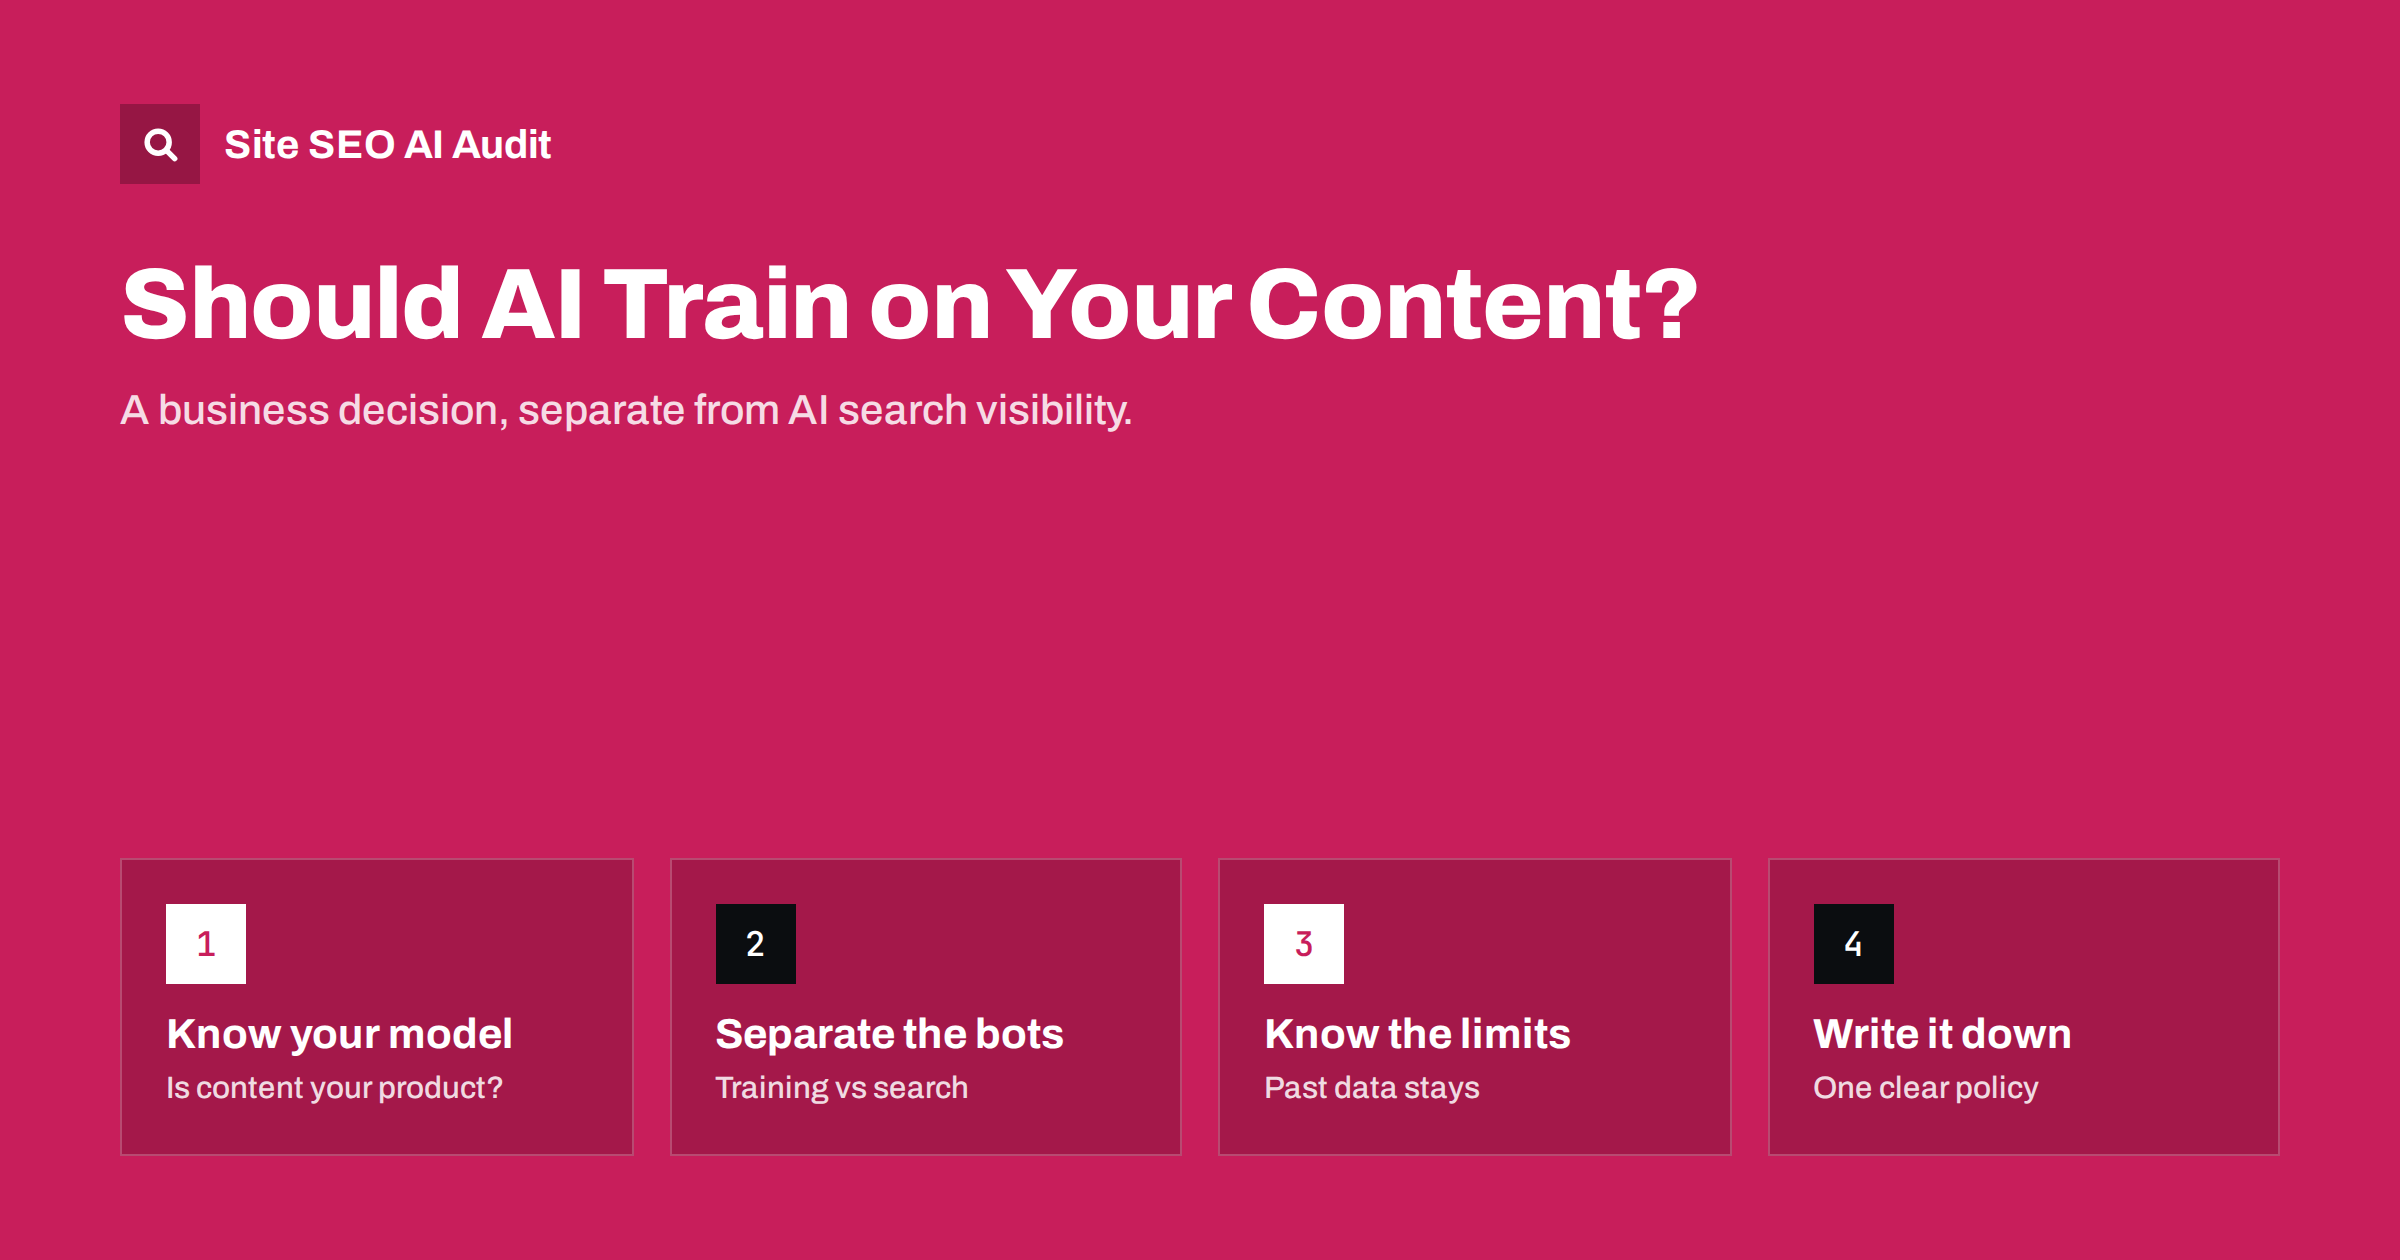
Short answer: Whether to let AI companies train on your content is a business decision, separate from whether you want to appear in AI search. If your content mainly markets products or services, allowing training can help models describe you accurately and costs little. If your content is itself the product, such as journalism, research, courses or original art, blocking training crawlers protects its value. In both cases you can keep AI search crawlers allowed, and you should know that blocking only affects future collection by operators that respect your rules.
Two different questions
Discussions about AI and websites often blur two separate questions:
- Training: may AI companies use your content to train or improve their models?
- Search and answers: may AI assistants retrieve your pages to answer users’ questions, usually with citations?
Major operators increasingly separate these with different crawlers and tokens. OpenAI uses GPTBot for training and OAI-SearchBot for search. Google uses the Google-Extended token for Gemini training and grounding, while Google Search, including AI Overviews, follows Googlebot. Other operators have their own names. This separation lets you make two independent decisions, and many sites choose differently for each.
Treating the two questions separately usually leads to better decisions. A business that would never block AI search, because it wants to be recommended, can still make a calm, independent choice about training.
Reasons to allow training
- Accurate descriptions. Models that have learned about your business from your own pages are more likely to describe your products, services and facts correctly, even when they answer without searching.
- Brand familiarity. Being part of what models know can make your brand more likely to come up in general answers about your category.
- Low cost for marketing content. If your pages exist to attract customers, their value lies in being read and repeated, not in exclusivity.
- Simplicity. Allowing everything means fewer rules to maintain and fewer accidental blocks of the crawlers you do want.
For many small businesses, these reasons add up to a clear answer: the content was written to be found and repeated, so there is little to protect and something to gain.
Reasons to block training
- Your content is your product. Publishers, educators, researchers and artists may see training as use of their work without compensation.
- Substitution risk. If models can reproduce the substance of your content, fewer people may need to visit or pay for it.
- Licensing opportunities. Some publishers negotiate licences with AI companies; keeping content out of free collection may strengthen that position.
- Legal or contractual constraints. Content licensed from third parties, client materials or regulated information may not be yours to offer for training.
- Principle. Some owners simply prefer not to contribute to model training, which is a legitimate choice.
Blocking training is not a statement against AI in general. Many publishers that block training crawlers still welcome AI search, because citations bring readers and recognition. Being precise about which use you object to keeps the benefits you want.
What blocking can and cannot do
| Blocking training crawlers will | Blocking training crawlers will not |
|---|---|
| Ask compliant operators not to collect your content from now on | Remove content already collected or used in existing models |
| Keep your future content out of their new training data, according to their policies | Stop non-compliant scrapers that ignore robots.txt |
| State your preference in a documented, recognised way | Remove your content from third-party datasets collected earlier |
| Leave AI search working if search crawlers remain allowed | Prevent users from pasting your content into assistants themselves |
Open datasets deserve a note. Common Crawl, collected by CCBot, is a widely used public web archive, and many models have been trained partly on it. Blocking CCBot affects future crawls, not archives already published.
Questions to ask before deciding
If the choice is not obvious, a few questions usually settle it. Discuss them with whoever owns the content and the business model, not only with the person who manages the website:
- How does this content make money? If it attracts customers to something else, wider reuse is mostly positive. If people pay for the content itself, reuse competes with you.
- Would we mind if a model could explain what our content explains? For a service page, probably not. For a paid course, probably yes.
- Do we own all of it? Guest posts, licensed photos, client case studies and supplier documents may carry restrictions.
- Are we likely to negotiate licences? Large publishers sometimes do; most small businesses do not.
- How would customers see it? Some audiences, particularly in creative fields, care strongly about how their community’s work is used.
The answers can differ between sections of the same site, which is why folder-level rules are often the best solution: marketing pages open, premium or licensed sections restricted.
A decision guide by type of site
- Local businesses, shops, SaaS and service companies: usually allow both training and search. Accurate model knowledge of your offer is an advantage.
- B2B companies with valuable guides: often allow both, but may block training for premium resources placed in specific folders.
- News publishers and content businesses: often block training crawlers and allow search crawlers, sometimes pending licensing agreements.
- Course providers and paid communities: keep paid content behind authentication; decide on public marketing pages separately.
- Artists and photographers: often block training where possible, and combine this with platform choices and licensing terms.
There is no universally correct answer. The important thing is to make a conscious decision rather than inheriting one from a plugin, a CDN default or a copied template.
Whatever you decide, revisit it once a year. The balance between exposure, licensing and protection is shifting quickly, and a choice that made sense when you made it may need adjusting as the market and the rules evolve.
How to implement your decision
- Write the policy in one or two sentences, for example “We allow AI search crawlers and block AI training crawlers on the whole site.”
- Update robots.txt with groups for the training crawlers and tokens you want to block, such as GPTBot, ClaudeBot, CCBot, Google-Extended and Applebot-Extended, and make sure search crawlers are not caught by the same rules.
- Check your CDN and security settings, which may already block some bots or offer AI-related toggles, and align them with the policy.
- Consider enforcement at the server or CDN if non-compliant scrapers are a concern.
- Review the list of bot names twice a year, because new crawlers appear and operators change names.
- Keep records of your policy and when it changed, which can matter for licensing or legal questions later.
After implementing the policy, check your server logs for a few weeks. Training crawlers that respect your rules should stop requesting blocked paths, while search crawlers continue as before. If a named training crawler keeps fetching blocked pages, verify that the requests really come from the operator before drawing conclusions, since user agents are easy to fake.
Legal context in brief
The legal position of AI training on web content is still developing and differs between countries. In the EU, copyright rules on text and data mining allow rights holders to reserve their works by machine-readable means, and robots.txt rules are widely used for this purpose, although exactly which signals count is still debated. Court cases in several countries are testing how copyright applies to training. If the question matters significantly for your business, get legal advice for your jurisdiction; this guide is not legal advice.
For most small businesses, a clear robots.txt policy, applied consistently, is the practical step that matters. Keep a dated copy of each version you publish.
How Site SEO AI Audit helps
Site SEO AI Audit reads your robots.txt and reports which AI crawlers are allowed and which are blocked, in the AI visibility area of its report. That makes it easy to confirm that your training policy is implemented as intended and, just as important, that AI search crawlers were not blocked by accident along the way. You can run a free audit to check your current rules.
Related reading
- How to Allow or Block AI Crawlers in robots.txt
- Google-Extended Explained: What Blocking It Does and Doesn’t
- noai and noimageai Meta Tags: Do They Actually Work?
- Paywalls, Logins and Gated Content in AI Search
The bottom line
Treat AI training and AI search as two separate decisions. Allow training if your content mainly markets what you sell and accurate model knowledge helps you; block it if your content is your product or comes with restrictions. Keep AI search crawlers allowed unless you have a strong reason not to, implement the policy consistently across robots.txt and your CDN, and remember that blocking shapes the future, not the past.
GYIK
Can I block AI training but still appear in AI search?
Yes. Major operators use separate crawlers or tokens for training and search. Block training crawlers such as GPTBot and keep search crawlers such as OAI-SearchBot allowed.
Does blocking GPTBot remove my content from existing models?
No. Robots.txt changes only affect future collection. Content already used in training is not removed by blocking the crawler now.
Is blocking AI training bad for my visibility?
It does not directly affect AI search if search crawlers remain allowed. It may mean models know less about you when answering without search, which matters more for businesses than for publishers.
Which crawlers are used for training?
Common examples include GPTBot, ClaudeBot and CCBot, plus tokens such as Google-Extended and Applebot-Extended. Check each operator’s documentation, as names and roles change.
Do all AI companies respect robots.txt?
Major operators say their documented crawlers do, but compliance is voluntary and some scrapers ignore it. Use server or CDN blocking where enforcement is important.