 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Crawling
Crawling is how search engines discover and download the pages of a website. Articles tagged here explain how crawlers find URLs through links and sitemaps and how they decide what to fetch again. They cover crawl budget, crawl traps, server errors and slow responses. Each guide shows how to see your site the way a crawler sees it. You will learn which fixes make crawling faster and cleaner. A page that is never crawled can never be indexed or ranked.
 2026/09/14 · 7分で読めます
Search Console Page Indexing Report: Every Status Explained
What each reason in Search Console's page indexing report means, which statuses are normal, which need action, and how to work through the report…
 2026/09/11 · 7分で読めます
WordPress Crawl Waste: Feeds, Attachments and Junk URLs
WordPress quietly creates many URLs nobody needs in search: attachment pages, feeds, date archives, search and parameter URLs. How to find and tame each…
 2026/09/05 · 8分で読めます
Mobile-First Indexing: What Must Match on Mobile and Desktop
Google indexes the mobile version of your pages. What must match between mobile and desktop: content, links, metadata, structured data and media.
 2026/09/04 · 7分で読めます
Technical SEO Audit Checklist: 40 Checks in the Right Order
A practical technical SEO audit checklist grouped by area, from indexability and redirects to speed and structured data, and the order to fix what…
 2026/09/01 · 8分で読めます
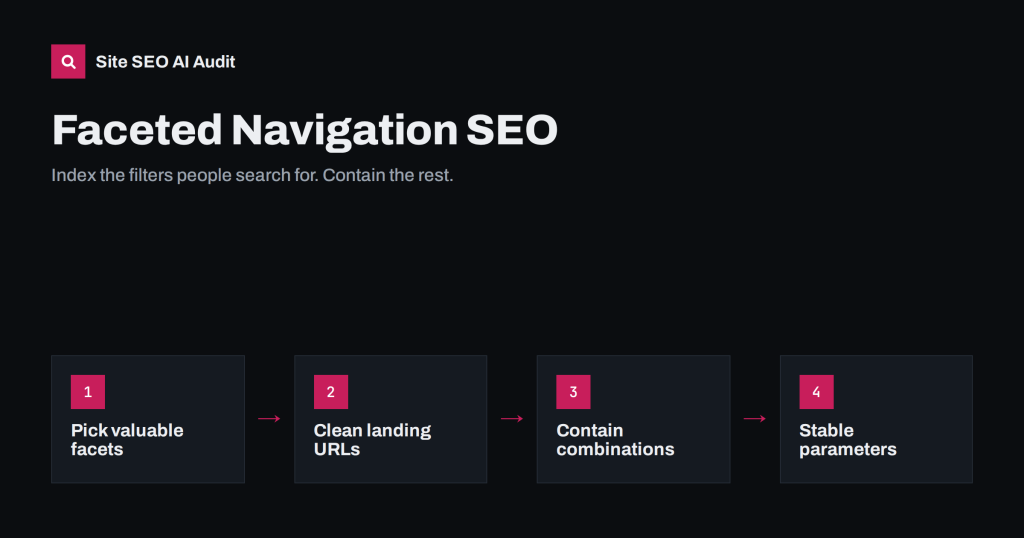
Faceted Navigation SEO: Filters Without Crawl Chaos
Shop filters can create millions of near-duplicate URLs. How to choose which filter pages to index, keep the rest out of the crawl and…
 2026/08/31 · 7分で読めます
Pagination SEO: How to Handle Page 2, 3 and Beyond
How to set up paginated categories and archives so search engines crawl every item: canonicals, links, titles, noindex myths, load-more and infinite scroll.
 2026/08/30 · 7分で読めます
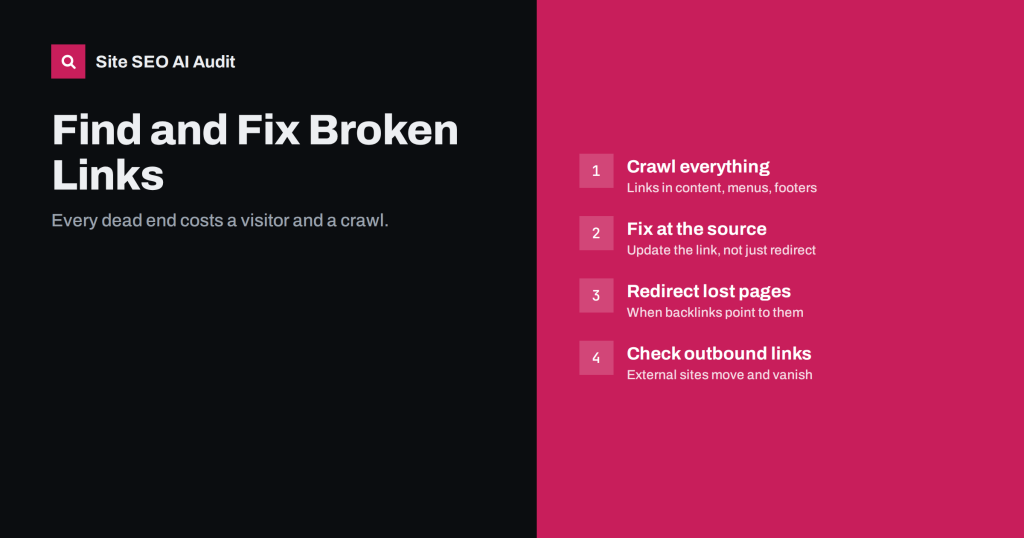
Broken Links: How to Find and Fix Them Across Your Site
Broken internal and external links frustrate visitors and waste crawling. Learn where they come from, how to find every one, and how to decide…
 2026/08/27 · 7分で読めます
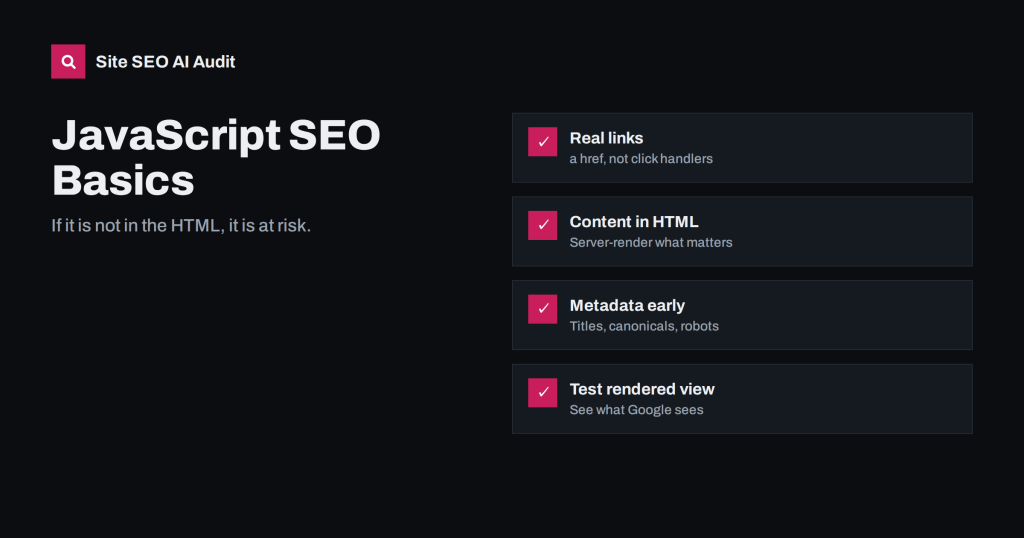
JavaScript SEO Basics: How Search Engines Render Your Pages
How Google crawls and renders JavaScript sites, where rendering fails, and the practical rules that keep content, links and metadata visible to search engines.
 2026/08/23 · 7分で読めます
Server Response Time and TTFB: How to Speed Up Your Server
Time to first byte explained: what slows a server response, how to measure it on every page, and the caching, hosting and database fixes…
 2026/08/16 · 7分で読めます
URL Parameters and Duplicate Content: A Practical Fix Guide
Tracking, sorting and filter parameters can turn one page into thousands of duplicate URLs. Here is how to decide which to keep, canonicalise, block…
 2026/08/15 · 8分で読めます
Discovered – Currently Not Indexed: Why and How to Fix It
Google knows these URLs but has not crawled them. Learn what the status says about crawl priority and server capacity, and how to get…
 2026/08/13 · 7分で読めます
HTTP Status Codes for SEO: The Ones That Actually Matter
A practical guide to HTTP status codes for SEO: what 200, 301, 302, 304, 404, 410, 429, 500 and 503 tell search engines and…