 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Duplicate content
Duplicate content means the same or nearly the same content is available at more than one URL. Articles tagged here explain where duplicates come from, including URL parameters, protocol and host variants, trailing slashes and filters. They show how search engines choose one version and why that choice may differ from yours. Each guide explains when to use canonicals, redirects or noindex. You will also learn how to find duplicates at scale with a crawl. Consolidating duplicates keeps signals focused on one strong page.
 13. 10. 2026 · Čtení: 8 min
Shopify Technical SEO: Duplicate URLs and Platform Limits
Shopify handles many SEO basics, but its URL structure, collection paths, tag pages and apps create typical problems. What to check and what you…
 12. 10. 2026 · Čtení: 8 min
Same Site on Two Domains: Fixing Cross-Domain Duplicates
Old domains, aliases and staging hosts can serve a full copy of your site. How to find every duplicate domain and consolidate it into…
 11. 10. 2026 · Čtení: 8 min
Manufacturer Product Descriptions and Duplicate Content
Hundreds of shops use the same manufacturer text, so search engines pick one page and filter the rest. How to stand out without rewriting…
 1. 10. 2026 · Čtení: 8 min
Duplicate Pages in AI Search: Which URL Gets Cited?
When several of your pages say the same thing, AI answers may cite the wrong one, or an outdated one. How duplicates affect AI…
 30. 9. 2026 · Čtení: 8 min
Boilerplate Text: How Repeated Blocks Affect Your Pages
Headers, footers, disclaimers and templated blocks repeat on every page. Learn when boilerplate is harmless, when it makes pages look alike and how to…
 30. 9. 2026 · Čtení: 7 min
Content Syndication and AI Search: Who Gets the Credit?
Republishing articles on bigger platforms can win reach but lose the citation. Learn how syndication affects search and AI answers, and how to keep…
 29. 9. 2026 · Čtení: 8 min
Internal Site Search Pages: Keep Them Out of the Index
Why internal site search result pages should usually stay out of Google, how to block them with noindex or robots.txt, and how to use…
 26. 9. 2026 · Čtení: 7 min
Index Bloat: How to Find and Clean Up Unwanted Indexed URLs
Index bloat means search engines hold many URLs you never meant to rank. How to measure it, which URL types cause it, and how…
 23. 9. 2026 · Čtení: 8 min
International SEO Myths That Waste Time and Budget
Common international SEO myths, from duplicate content penalties for translations to hreflang boosting rankings, and what actually works for multilingual sites.
 22. 9. 2026 · Čtení: 8 min
What to Do With Untranslated Pages on a Multilingual Site
When a page has no translation, should the translated URL show the original, redirect or not exist? The SEO trade-offs and a clean set-up…
 16. 9. 2026 · Čtení: 8 min
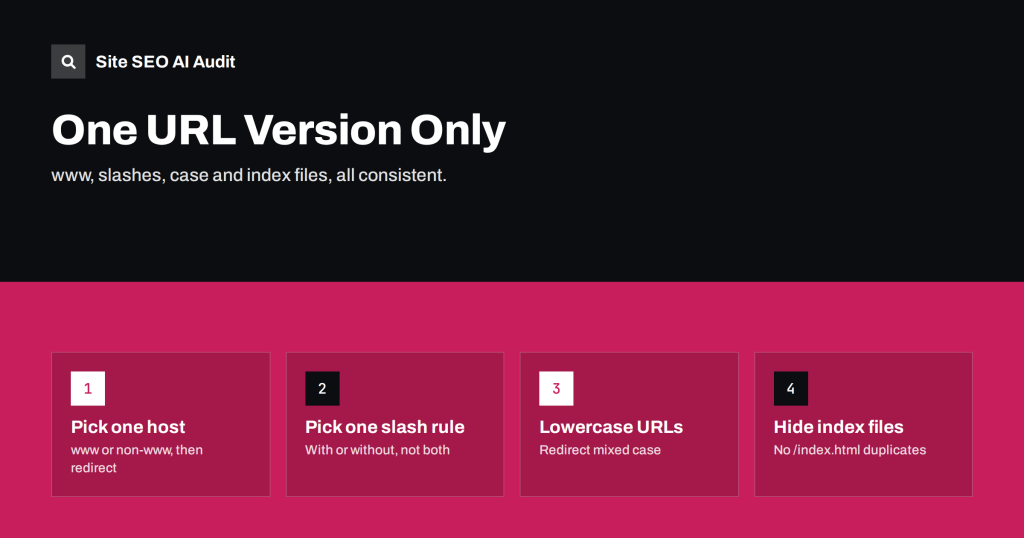
WWW, Trailing Slashes and Case: One URL Version Only
www or non-www, with or without a trailing slash, upper or lower case: how URL variants split signals, and how to pick one version…
 13. 9. 2026 · Čtení: 8 min
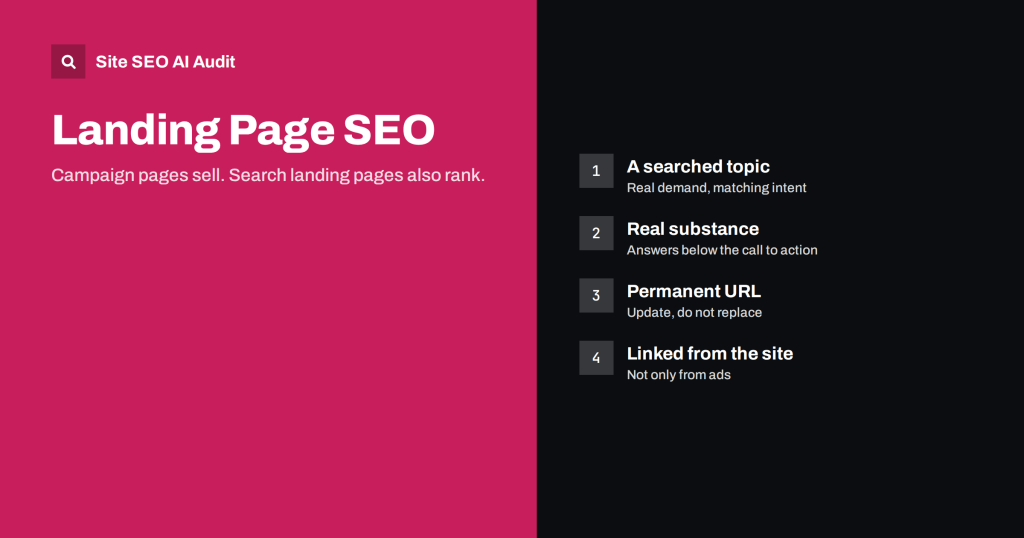
Landing Page SEO: How to Build Landing Pages That Can Rank
Why most campaign landing pages never rank, and how to build search landing pages that can: topic, intent, substance, permanent URLs, links and variants.