 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Indexing
Indexing is the step where a search engine decides to store a page and make it eligible to appear in results. Articles tagged here explain noindex, canonical selection, duplicate handling and the Search Console indexing statuses. They show why a crawled page may still be left out of the index. Each guide lists the checks to run before asking for reindexing. You will also learn how to remove pages that should not be indexed. Clean indexing keeps the right pages visible and the rest out of the way.
 06.08.2026 · 7 Min. Lesezeit
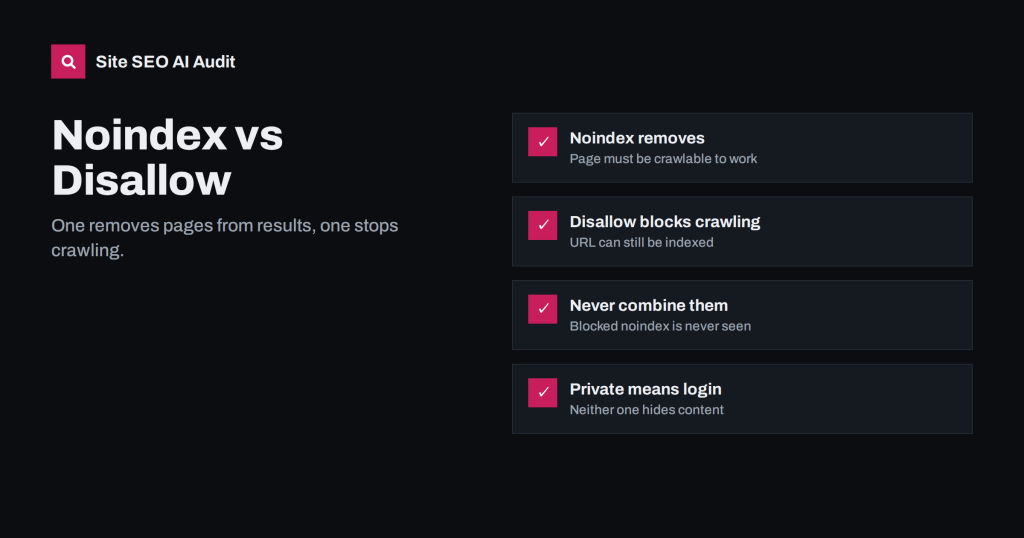
Noindex vs Disallow: How to Keep Pages Out of Search
Noindex and robots.txt Disallow solve different problems. Learn which removes pages from search, which saves crawl time, and why combining them backfires.
 03.08.2026 · 8 Min. Lesezeit
XML Sitemap Best Practices: What to Include and Leave Out
How to build an XML sitemap search engines trust: which URLs belong in it, which do not, size limits, lastmod, sitemap indexes and how…
 02.08.2026 · 8 Min. Lesezeit
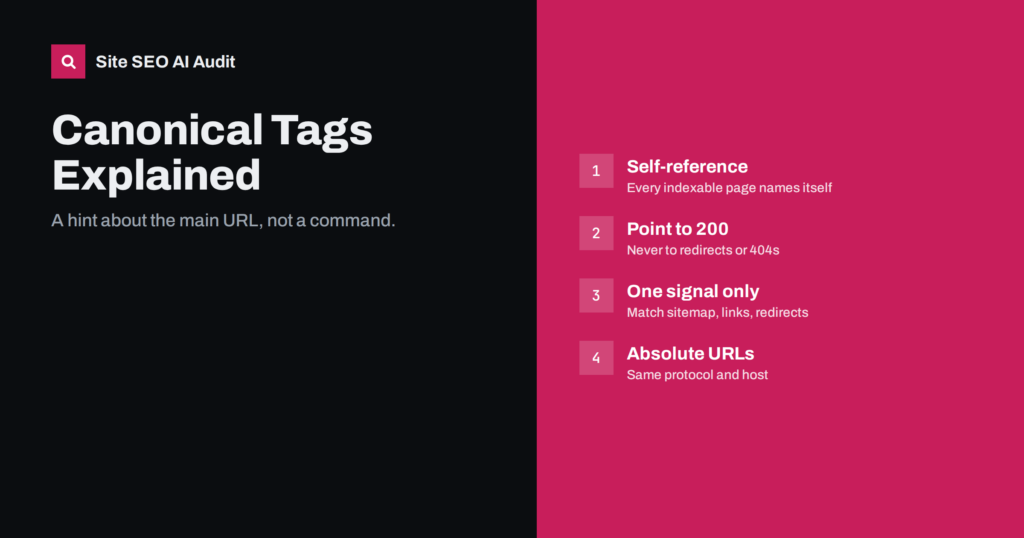
Canonical Tags Explained: How to Set Them and Fix Errors
What a canonical tag does, when search engines ignore it, the canonical errors audits find most often, and how to fix each one without…