 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Duplicate content
Duplicate content means the same or nearly the same content is available at more than one URL. Articles tagged here explain where duplicates come from, including URL parameters, protocol and host variants, trailing slashes and filters. They show how search engines choose one version and why that choice may differ from yours. Each guide explains when to use canonicals, redirects or noindex. You will also learn how to find duplicates at scale with a crawl. Consolidating duplicates keeps signals focused on one strong page.
 11 sept. 2026 · 7 min de lecture
Blog Category and Tag Pages: How to Make Them Useful for SEO
How to manage blog category and tag pages for SEO: when archives help or hurt, a clean category structure, a tag policy, descriptions and…
 1 sept. 2026 · 8 min de lecture
Faceted Navigation SEO: Filters Without Crawl Chaos
Shop filters can create millions of near-duplicate URLs. How to choose which filter pages to index, keep the rest out of the crawl and…
 22 août 2026 · 8 min de lecture
Location Pages for SEO: How to Avoid Duplicate City Pages
How to build location pages that help: branch vs service area pages, what makes each page unique, how many to create and how to…
 20 août 2026 · 8 min de lecture
Category Page SEO: How to Make Store Categories Rank
How to optimize e-commerce category pages: category structure, titles and H1s, short useful introductions, product grids, filters and internal links.
 19 août 2026 · 8 min de lecture
Product Page SEO: How to Optimize E-commerce Product Pages
How to optimize e-commerce product pages: titles, original descriptions, images, price and reviews, structured data, variants and out-of-stock products.
 17 août 2026 · 8 min de lecture
Same Language, Different Countries: How to Target en-US and en-GB
How to run separate pages for the US, UK, Australia or Spain and Mexico without duplicate trouble: when to split, what to change and…
 16 août 2026 · 7 min de lecture
URL Parameters and Duplicate Content: A Practical Fix Guide
Tracking, sorting and filter parameters can turn one page into thousands of duplicate URLs. Here is how to decide which to keep, canonicalise, block…
 14 août 2026 · 8 min de lecture
Crawled – Currently Not Indexed: Causes and Real Fixes
Why Google crawls a page but leaves it out of the index, how to tell a quality problem from a technical one, and the…
 11 août 2026 · 8 min de lecture
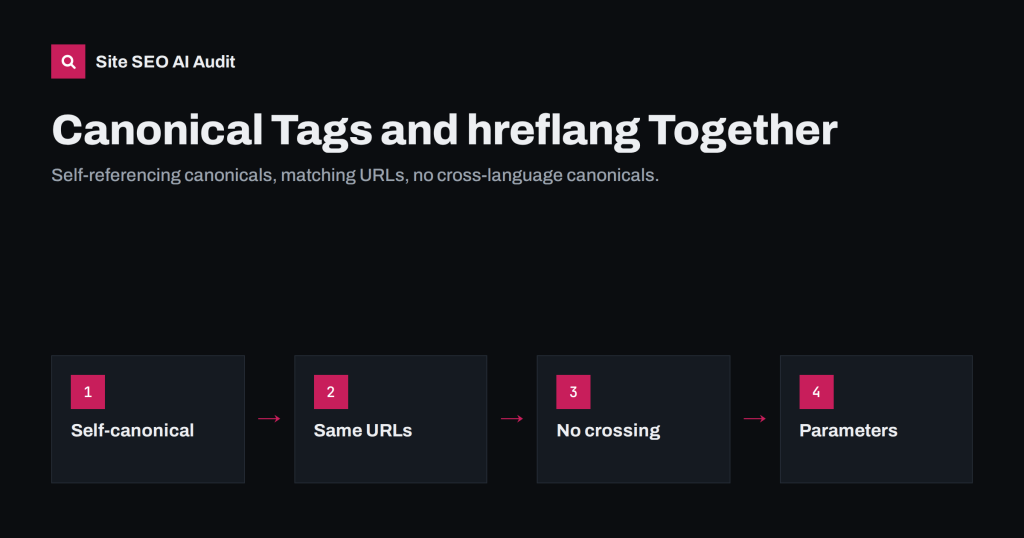
Canonical Tags and hreflang: How to Use Them Together
Canonical tags and hreflang answer different questions. Learn how to combine them and avoid the cross-language canonical that cancels hreflang.
 10 août 2026 · 8 min de lecture
Keyword Cannibalization: How to Spot It and Fix It
What keyword cannibalization really is, how to confirm it in Search Console, when overlap is harmless, and how to merge, refocus or canonicalize pages.
 9 août 2026 · 8 min de lecture
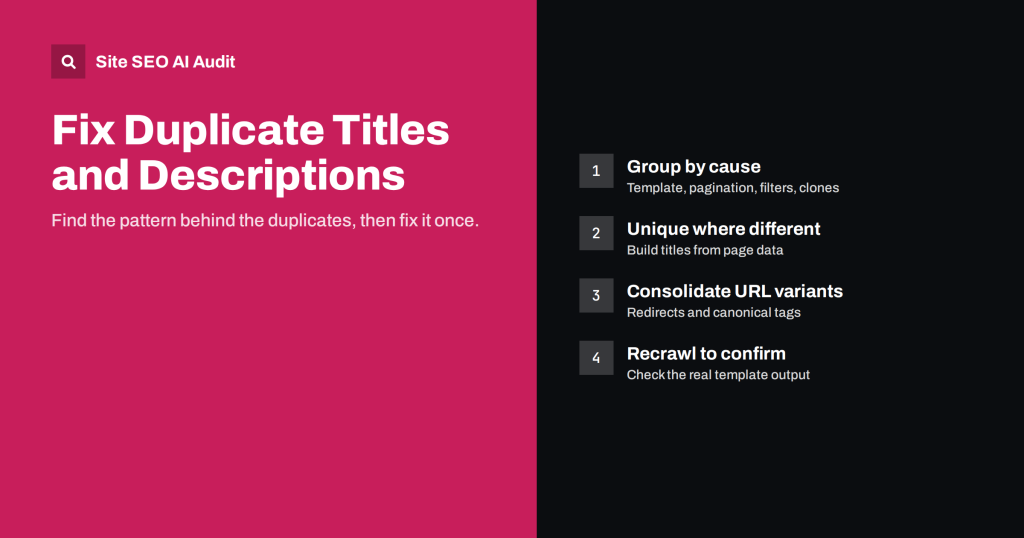
Duplicate Title Tags and Meta Descriptions: How to Fix Them
Why pages end up with duplicate titles and meta descriptions, how to group them by cause, and how to fix templates, URL variants and…
 2 août 2026 · 8 min de lecture
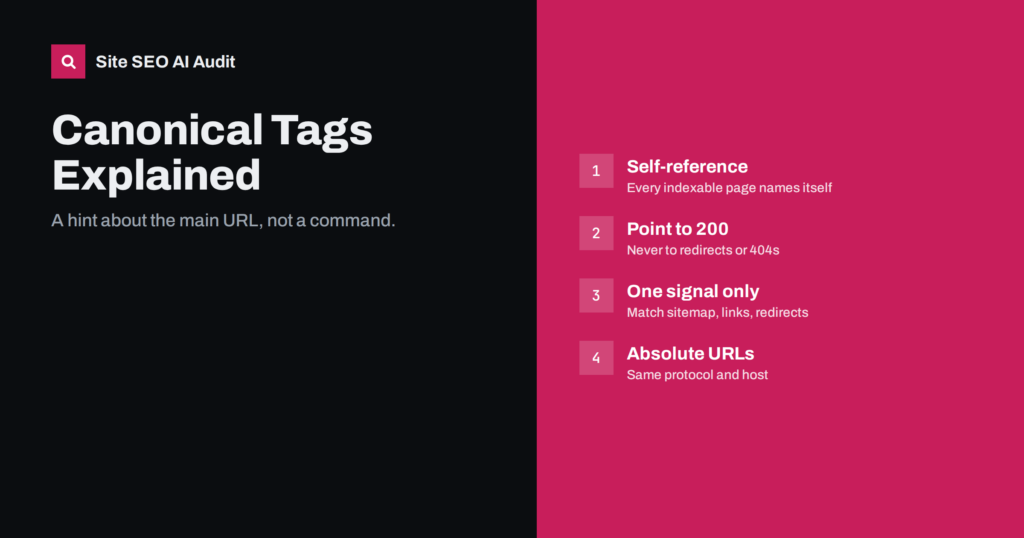
Canonical Tags Explained: How to Set Them and Fix Errors
What a canonical tag does, when search engines ignore it, the canonical errors audits find most often, and how to fix each one without…