 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Duplicate content
Duplicate content means the same or nearly the same content is available at more than one URL. Articles tagged here explain where duplicates come from, including URL parameters, protocol and host variants, trailing slashes and filters. They show how search engines choose one version and why that choice may differ from yours. Each guide explains when to use canonicals, redirects or noindex. You will also learn how to find duplicates at scale with a crawl. Consolidating duplicates keeps signals focused on one strong page.
 Oct 1, 2026 · 8 min read
Duplicate Pages in AI Search: Which URL Gets Cited?
When several of your pages say the same thing, AI answers may cite the wrong one, or an outdated one. How duplicates affect AI…
 Sep 30, 2026 · 8 min read
Boilerplate Text: How Repeated Blocks Affect Your Pages
Headers, footers, disclaimers and templated blocks repeat on every page. Learn when boilerplate is harmless, when it makes pages look alike and how to…
 Sep 30, 2026 · 7 min read
Content Syndication and AI Search: Who Gets the Credit?
Republishing articles on bigger platforms can win reach but lose the citation. Learn how syndication affects search and AI answers, and how to keep…
 Sep 29, 2026 · 8 min read
Internal Site Search Pages: Keep Them Out of the Index
Why internal site search result pages should usually stay out of Google, how to block them with noindex or robots.txt, and how to use…
 Sep 26, 2026 · 7 min read
Index Bloat: How to Find and Clean Up Unwanted Indexed URLs
Index bloat means search engines hold many URLs you never meant to rank. How to measure it, which URL types cause it, and how…
 Sep 23, 2026 · 8 min read
International SEO Myths That Waste Time and Budget
Common international SEO myths, from duplicate content penalties for translations to hreflang boosting rankings, and what actually works for multilingual sites.
 Sep 22, 2026 · 8 min read
What to Do With Untranslated Pages on a Multilingual Site
When a page has no translation, should the translated URL show the original, redirect or not exist? The SEO trade-offs and a clean set-up…
 Sep 16, 2026 · 8 min read
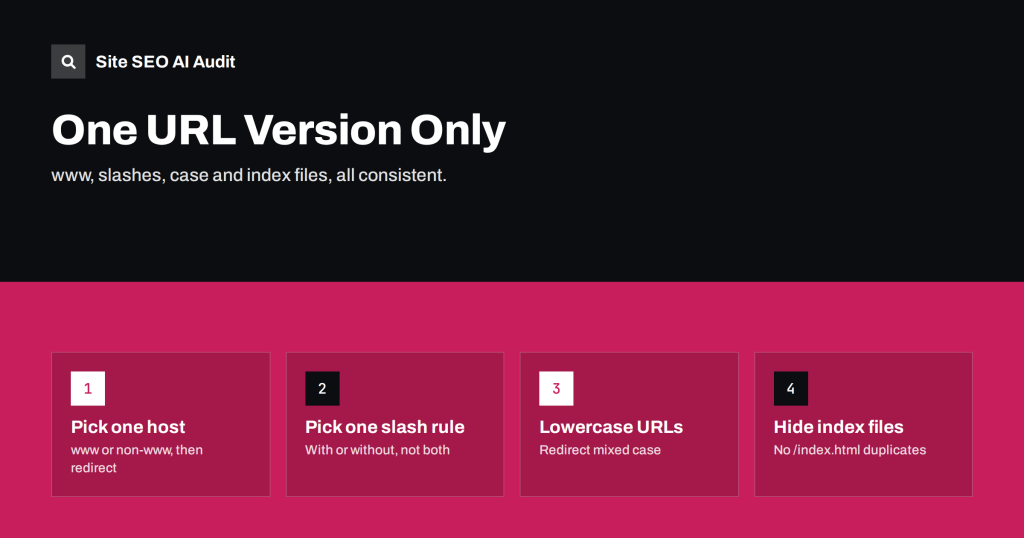
WWW, Trailing Slashes and Case: One URL Version Only
www or non-www, with or without a trailing slash, upper or lower case: how URL variants split signals, and how to pick one version…
 Sep 13, 2026 · 8 min read
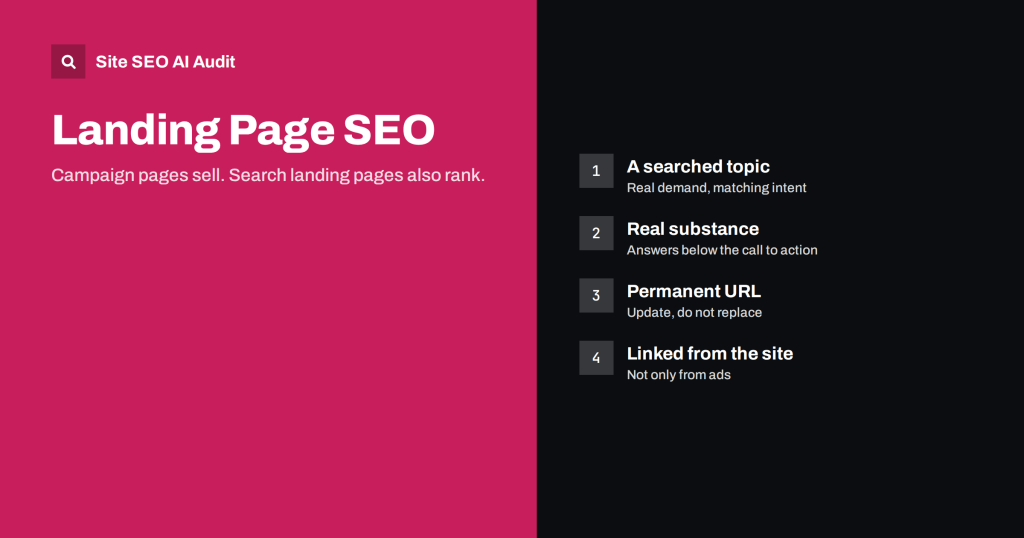
Landing Page SEO: How to Build Landing Pages That Can Rank
Why most campaign landing pages never rank, and how to build search landing pages that can: topic, intent, substance, permanent URLs, links and variants.
 Sep 11, 2026 · 7 min read
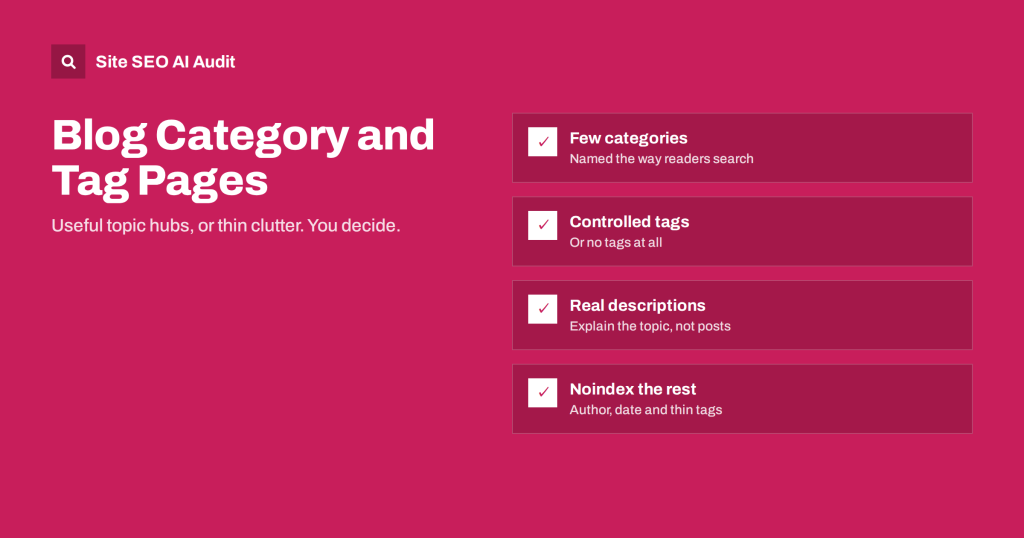
Blog Category and Tag Pages: How to Make Them Useful for SEO
How to manage blog category and tag pages for SEO: when archives help or hurt, a clean category structure, a tag policy, descriptions and…
 Sep 1, 2026 · 8 min read
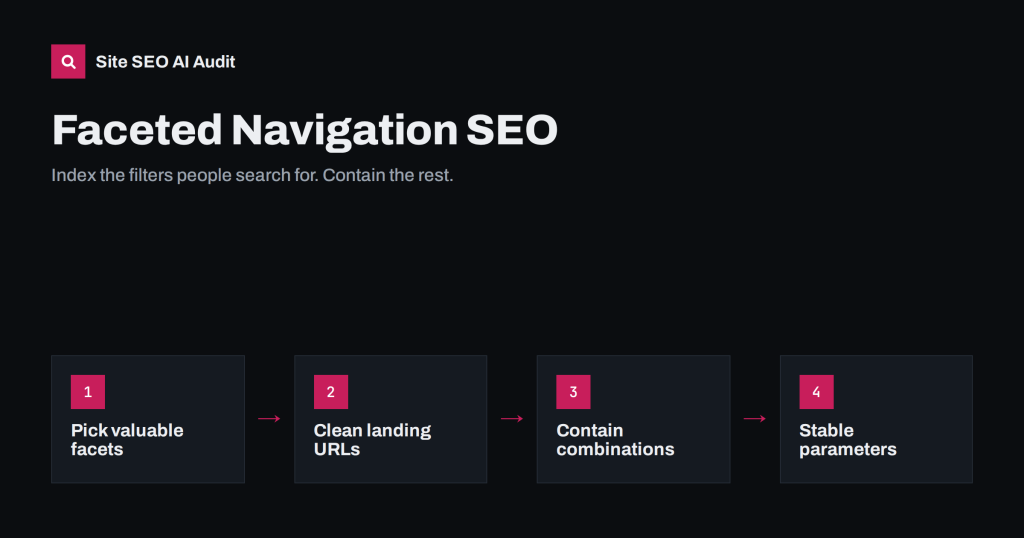
Faceted Navigation SEO: Filters Without Crawl Chaos
Shop filters can create millions of near-duplicate URLs. How to choose which filter pages to index, keep the rest out of the crawl and…
 Aug 22, 2026 · 8 min read
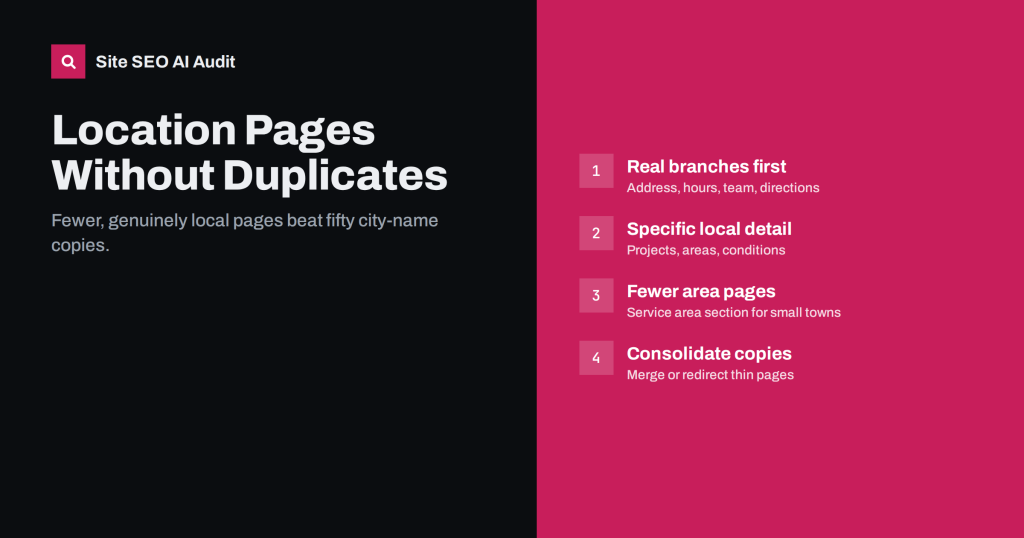
Location Pages for SEO: How to Avoid Duplicate City Pages
How to build location pages that help: branch vs service area pages, what makes each page unique, how many to create and how to…