 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
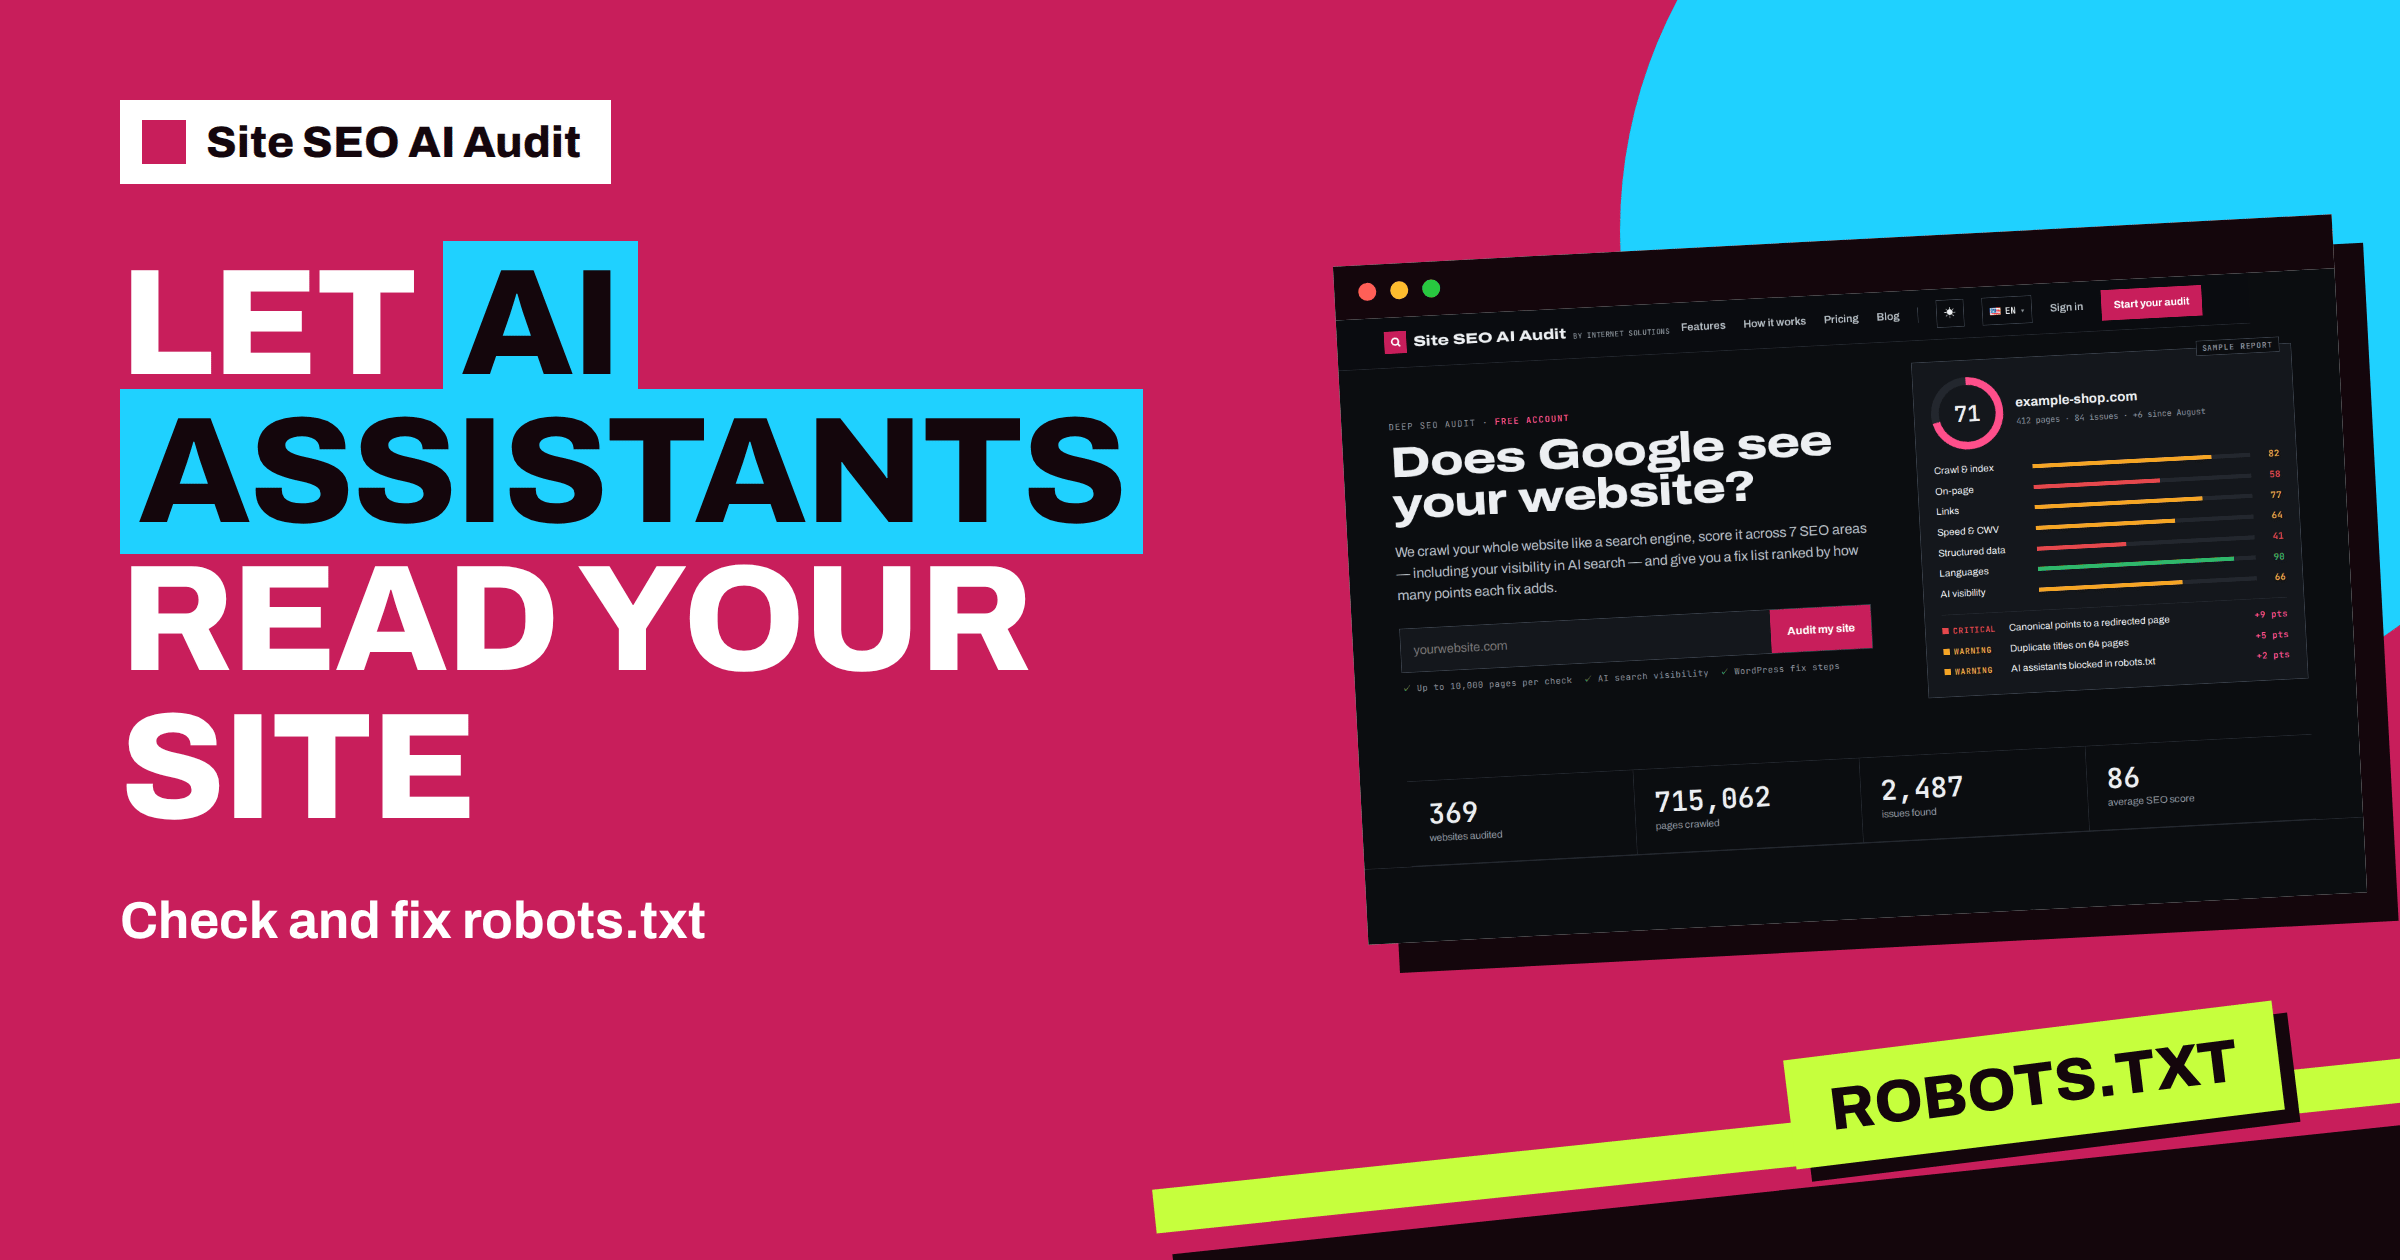
Short answer: In Site SEO AI Audit, the warning “AI assistants are blocked in robots.txt” means your robots.txt file tells AI crawlers not to read your site, so your content cannot be read or cited by AI search and assistants. The sample report on the home page lists it as worth two points. Open your robots.txt, find the rules for AI crawlers, decide which ones you really want to block, remove or narrow the rest and run a new check to see the AI visibility area recover.
For years, robots.txt was a file that only search engine specialists opened. Now it also decides whether AI assistants can read your pages when someone asks a question about your business. Many owners never chose to block these crawlers. A security plugin, a hosting setting, a copied template or a quick fix by a developer did it for them. The audit makes this visible in one line of the report. This article explains how to read that line, what to decide and how to fix the file without breaking anything else.
What the warning means
The issue belongs to the AI visibility area, which carries eight percent of the total score. Its card says: your content cannot be read or cited by AI search and assistants. The fix is short: allow the AI crawlers you want to be visible in. The check reads your robots.txt, evaluates the rules that apply to the AI crawlers it knows and reports when one or more of them are disallowed.
The report also shows the result in its key figures. Next to the number of pages crawled and the number of critical issues, one tile shows the state of AI crawlers: either “Open” or the number that are blocked. That tile is a quick way to see where you stand before you read anything else.
Notice the word “warning”, not “critical”. The product does not claim that blocking AI crawlers is always wrong. It claims that blocking has a price, which is lower visibility in AI answers, and it makes sure you know about it. A business that has decided to block them can accept the warning. A business that never decided should look closer.
Read your robots.txt
Open your robots.txt by adding /robots.txt to your domain in the browser. The file is a list of groups. Each group begins with a line naming a crawler, followed by rules for what it may or may not fetch. Three patterns matter for this warning:
- A group for every crawler that disallows everything. A rule that applies to all crawlers and disallows the whole site blocks AI crawlers too, but it also blocks search engines. The audit reports that separately as a critical issue and caps the score.
- A group that names an AI crawler and disallows it. This is the typical source of the warning. Someone added a block for one or several named crawlers.
- A broad rule on parts of the site. Disallowing the folder that contains your articles, products or guides blocks the pages that AI assistants would most like to quote.
If you see a long list of unfamiliar names, do not panic. Many lists are copied from public templates that block every known AI crawler at once. The article on AI crawlers and robots.txt explains what the common ones are and what they are used for.
Decide what you want
There are good reasons to block some AI crawlers, and good reasons to allow them. The decision is business-specific, and it is best made on purpose. Think about the questions below.
| Question | If yes |
|---|---|
| Do customers ask AI assistants about my products or services? | Allow the crawlers that fetch pages to answer questions |
| Is my content paid, licensed or exclusive? | Consider blocking, or allow only the public pages |
| Do I object to my text being used to train models? | Block the crawlers that are used for training, and read their documentation |
| Is my site mostly local services, shops or advice? | Visibility in AI answers usually helps; allow public pages |
Some AI operators publish separate crawlers for training and for answering user questions, so you can often allow one purpose and block the other. The guide to the AI training opt-out decision walks through the trade-offs. The audit does not decide for you. It simply shows that a decision, or an accident, is present in the file.
Fix the file step by step
- Copy the current robots.txt into a safe place. You will want to compare it later.
- Mark each AI-related group as “intended” or “not intended”. If you do not know why a group is there, find out who added it: a plugin, the hosting panel or the CDN.
- Remove or narrow the unintended rules. Delete the group, or change it so that only the private areas, such as account pages, are disallowed.
- Find the source. If a plugin or a platform setting writes the rules, changing the file by hand may be undone at the next update. Turn the setting off at the source.
- Keep the rest intact. Do not remove the line that points to your sitemap, and do not change rules for search engines unless you mean to.
- Test the result. Open /robots.txt again, make sure it loads with status 200 and read it once more.
- Run a new check. Starter, Pro and Agency include re-checks. The warning should disappear, and the AI crawlers tile should read “Open”.
If the file is generated by a protective layer in front of your website, the fix may sit there rather than in the website itself. The article on CDNs and firewalls blocking AI crawlers covers this case, which is common on sites with strict security settings.
Blocking in robots.txt is only one layer
It is worth knowing that robots.txt is a request, not a lock, and it is only one place where AI access can be stopped. A firewall can return errors to unknown bots. A rate limit can slow them until they give up. A login wall hides pages entirely. The audit’s warning covers the robots.txt layer. If your robots.txt is open and the report still shows many errors, read the article on how SEOAuditBot behaves to understand what a crawler experiences, and consider checking your server logs for AI crawler requests, as described in the guide to AI crawlers in server logs.
A before and after example
Imagine a small consulting firm whose robots.txt contains a group for a named AI crawler with a rule that disallows the entire site. The owner never asked for it; a performance plugin added it during an update. The audit shows the warning, and the AI crawlers tile reads “1 blocked”. The fix is to delete that group, leave the group for all crawlers untouched and keep the sitemap line at the bottom. After the change, the owner opens the file, confirms that it loads, clears the cache and runs a new check. The warning is gone and the tile reads “Open”.
The difference is small in the file and large in effect. Before the change, an assistant asked about local consultants could not read the firm’s service pages at all. After it, the pages can be read, so the quality of the content, its structure and its dates decide whether it is quoted. That is the point of the AI visibility area: first access, then quality.
Talk to the people who touch the file
Robots.txt is often edited by more than one person: a developer, a hosting provider, a marketing consultant or an agency. Before you change it, ask who owns the file and whether any rule was added for a reason you do not know, such as protecting a staging area or a private download folder. Write the decision down, including the date and the reason, so that the next person does not restore the block by mistake. A short note in your SEO changelog is enough.
The rest of the AI visibility area
Opening the door is the first step. The same area also checks whether you have an llms.txt file, which is a short guide to your site for AI assistants, whether the main text of your pages needs JavaScript to appear, whether long pages have subheadings and whether articles show a publication date. Fixing the robots.txt warning but leaving these open leaves value on the table. Treat the area as a short checklist: allow access, give a guide, make the text readable in the HTML, structure it and date it. The explanation of llms.txt shows how simple the guide file can be.
To see where your own site stands, create a free account and run your check. The free account runs one check and shows the report locked, and any plan on the pricing page unlocks the issue list, the affected pages and the fixes.
Related reading
The bottom line
The warning shows that your robots.txt blocks AI crawlers. Decide on purpose which ones you want to allow, remove the accidental rules at their source, keep your search engine rules intact and run a new check to confirm that the AI crawlers tile reads “Open”.
FAQ
Is blocking AI crawlers always a mistake?
No. The report shows it as a warning because it lowers visibility in AI answers. If you blocked them on purpose, you can accept the warning.
Where do I find my robots.txt?
Add /robots.txt to your domain in the browser. The file lists the rules for each crawler.
Why are rules there that I never wrote?
A security plugin, a hosting setting, a CDN or a copied template may have added them. Find the source and change it there.
How many points can the fix add?
In the sample report on the home page the warning is worth two points. Your own number depends on how the AI visibility area scores your site.
What else does the AI visibility area check?
llms.txt, content that needs JavaScript, structure of long pages and publication dates on articles.


